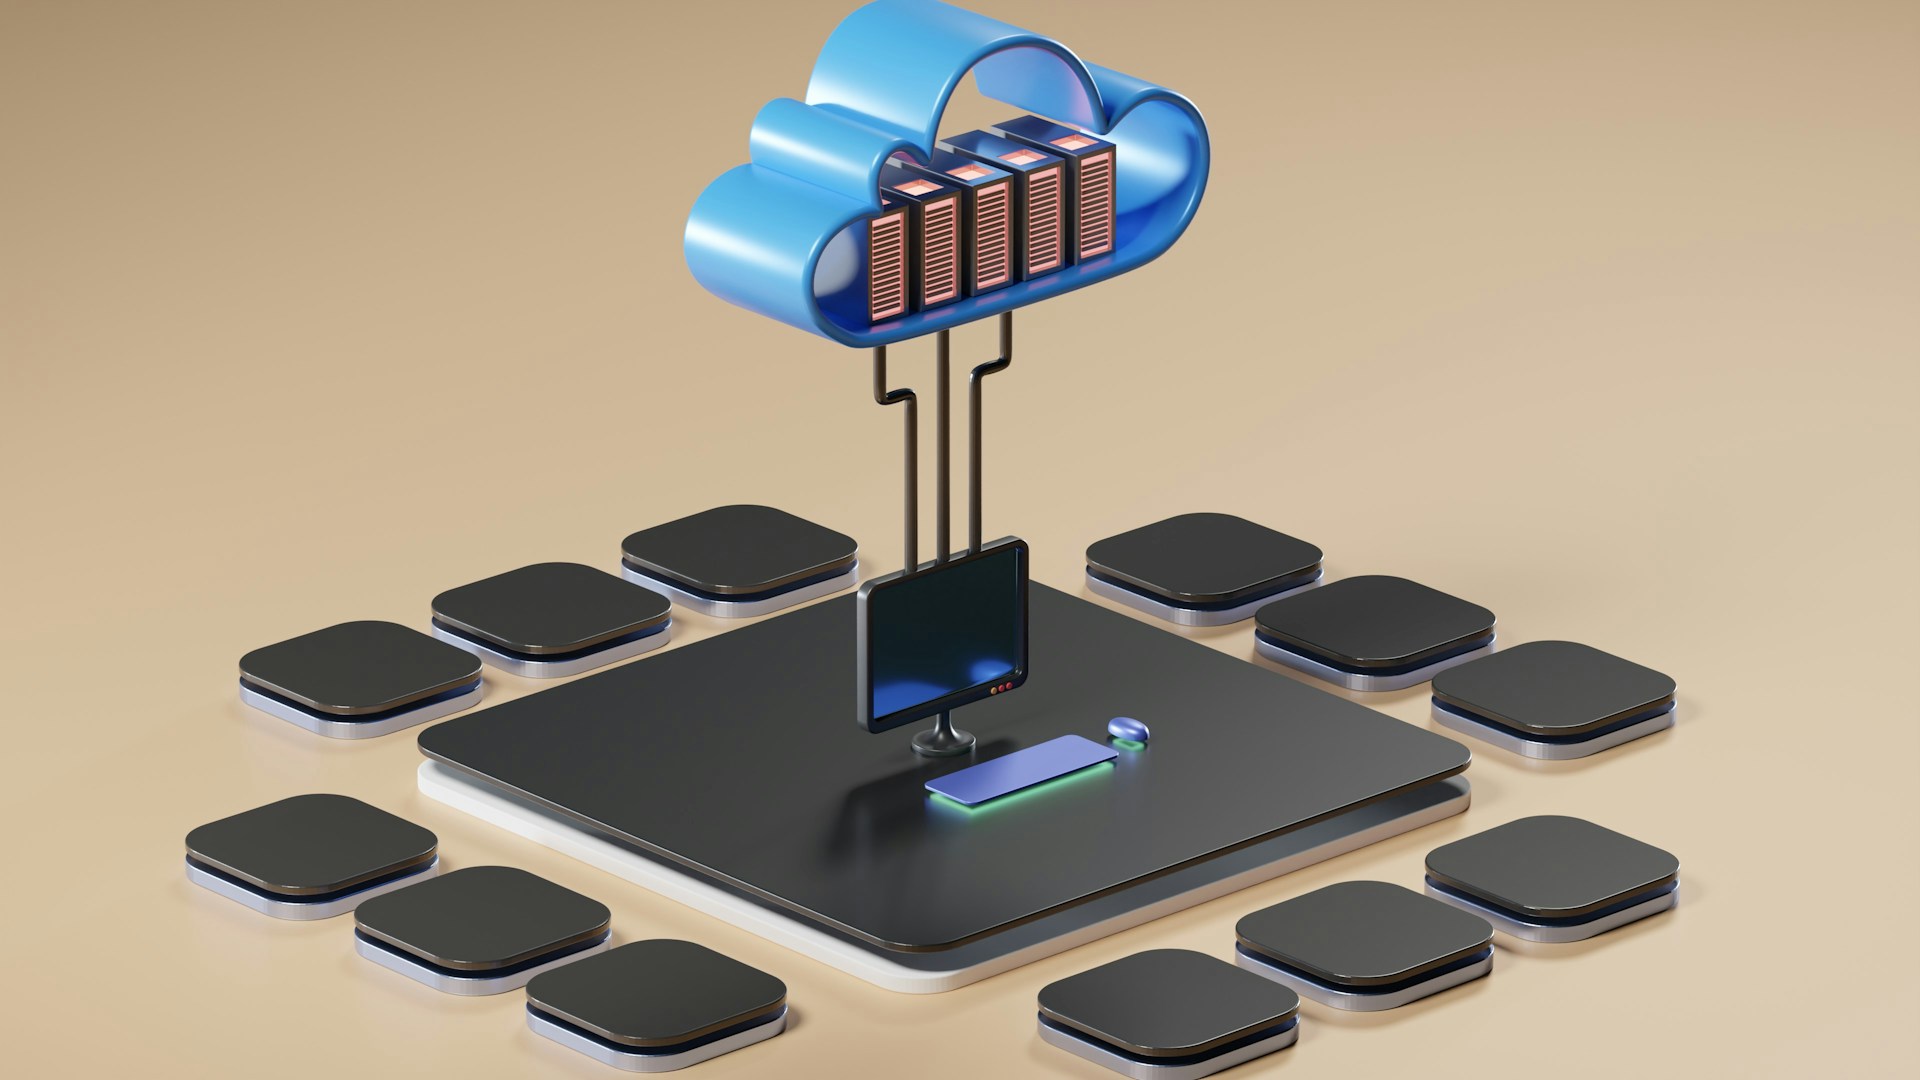
Serverless Computing in 2026: What It Is, When It Wins, and When It Doesn’t
Serverless computing has moved from a niche architecture pattern to a mainstream option for building and scaling applications. In 2026 it powers everything from simple event handlers to production APIs, background jobs, and parts of AI inference pipelines. Yet the term still confuses many teams: there are servers — you just do not manage them.
This guide explains serverless computing in plain language, covers how it actually works, lays out the real advantages and trade-offs, and gives clear guidance on when it is the right choice (and when it is not).
Quick Answer: What Is Serverless Computing?
Serverless computing is a cloud execution model in which the cloud provider fully manages the servers, capacity planning, and scaling. You deploy code (usually as functions or lightweight containers), and the platform runs it only when needed. You pay primarily for actual execution time and resources consumed rather than for idle capacity.
Popular implementations include AWS Lambda, Google Cloud Functions / Cloud Run, Azure Functions, Cloudflare Workers, and similar platforms from other providers.
How Serverless Computing Works
In a traditional model you provision virtual machines or containers, keep them running, patch them, and scale them yourself (or with tools you configure). In a serverless model:
- You write a function or small service that responds to an event (HTTP request, file upload, queue message, schedule, etc.).
- You upload the code to the provider.
- The platform automatically provisions the compute environment when the event arrives, runs your code, then scales the environment down (often to zero) when demand drops.
- You are billed for the duration and resources used during execution.
The “serverless” label refers to the absence of server management for the application team, not the absence of physical or virtual servers in the data center.
Core Benefits of Serverless Computing
1. No infrastructure management
Teams stop spending time on OS patching, capacity planning, load-balancer configuration, and many routine operational tasks. Engineering effort shifts toward product logic.
2. Automatic scaling (including scale-to-zero)
The platform handles sudden traffic spikes and quiet periods. For workloads with highly variable or unpredictable demand, this removes a major operational burden.
3. Pay-per-use economics
You primarily pay for what runs. Idle time costs little or nothing on most pure function platforms. This can be dramatically cheaper than always-on servers for spiky or low-duty-cycle workloads.
4. Faster experimentation and delivery
Small, focused functions can be deployed independently. Many teams ship features faster because the infrastructure layer is already solved.
5. Built-in high availability (within provider limits)
Major platforms distribute execution across availability zones and handle many failure modes automatically.
These advantages explain why serverless appears frequently in modern automation stacks and event-driven systems — the same systems that support efficient operations and selective AI automation in SaaS environments (see related practical guidance on AI automation for SaaS teams).
Real Limitations and Trade-offs
Serverless is not free of constraints. The most important ones in 2026 remain:
Cold starts
When a function has not run recently, the platform may need to initialize a new execution environment. This adds latency (sometimes tens to hundreds of milliseconds, occasionally more). For user-facing APIs that must feel instantaneous, cold starts still matter, although providers have improved them significantly.
Execution time and resource limits
Most function platforms impose maximum runtimes, memory ceilings, and package-size limits. Long-running processes, heavy computation, or large dependencies can push you outside the comfortable serverless envelope.
Vendor lock-in and proprietary services
Event sources, identity systems, and supporting services are often tightly integrated with one cloud. Moving a complex serverless application to another provider is rarely trivial.
Observability and debugging complexity
Distributed functions can be harder to trace than a monolithic service running on a known set of instances. Mature teams invest in structured logging, tracing, and alerting early.
Cost surprises at high, steady volume
Pay-per-use is excellent for spiky traffic. For high, constant throughput, reserved or always-on capacity (containers, VMs, or specialized serverless offerings with different pricing) can become cheaper.
Stateful and connection-heavy workloads
Persistent database connection pools, long-lived WebSocket connections, and certain high-performance networking patterns often fit poorly with pure function models.
When Serverless Computing Makes Sense
Strong fit:
- Event-driven background work (image/video processing, webhooks, notifications, file transformations)
- APIs and microservices with variable or bursty traffic
- Scheduled jobs and lightweight cron-style tasks
- Prototypes, internal tools, and early-stage products where speed of iteration matters more than squeezing every millisecond
- Glue logic between services (especially inside a single cloud ecosystem)
- Certain AI inference or agent endpoints that are invoked intermittently
Weaker fit:
- Latency-critical, always-on user-facing services that cannot tolerate cold starts
- Long-running batch jobs that exceed function timeouts
- Workloads with very high, steady traffic where dedicated capacity is more economical
- Systems that require fine-grained control over networking, specialized hardware, or complex stateful behavior
Many mature architectures are hybrid: serverless for the event-driven and spiky parts, containers or managed services for the steady-state core.
Serverless in the Broader 2026 Technology Landscape
Serverless sits alongside containers, managed Kubernetes, edge computing, and traditional virtual machines. It is especially relevant as companies invest heavily in AI infrastructure and agentic systems. When AI workloads are invoked on demand rather than running continuously, serverless-style execution can keep costs aligned with actual usage — a practical concern given the scale of AI spending tracked in current industry analyses.
For founders and technical leaders building new products, serverless often reduces early operational load so the team can focus on validation, brand, and distribution (themes explored in broader founder and digital-strategy resources on this site).
Practical Decision Framework
Ask these questions before choosing serverless for a given component:
- Is the workload event-driven or request-driven with variable demand?
- Can it tolerate occasional cold-start latency?
- Does it stay within typical execution-time and memory limits?
- Is the team prepared to adopt the provider’s observability and deployment model?
- Have you modeled costs at both low and high usage scenarios?
If most answers are “yes,” serverless is likely a strong candidate. If several answers are “no,” evaluate containers (Cloud Run, Fargate, etc.) or more traditional compute.
Getting Started Responsibly
- Begin with a single, well-bounded use case rather than rewriting an entire application.
- Instrument early (logs, metrics, traces).
- Set budget alerts and review actual spend after traffic patterns stabilize.
- Design functions to be stateless and idempotent where possible.
- Keep an exit strategy in mind — abstract provider-specific details behind clear interfaces when the cost of doing so is reasonable.
Bottom Line
Serverless computing in 2026 is a mature, powerful option for the right workloads. It removes large amounts of infrastructure toil, scales automatically, and aligns cost with actual usage. It is not a universal replacement for all compute.
Teams that treat it as one tool in a broader architecture — rather than a religion — capture the benefits while avoiding the common pitfalls. Match the execution model to the shape of the work, measure real performance and cost, and keep the design simple enough that the next engineer can understand it.
That pragmatic approach continues to separate effective engineering organizations from those that chase architectural trends without clear payoff.
About the Author
Written by the LA Tech Post editorial team. We analyze technology strategy, infrastructure patterns, and AI-era operating models with a focus on practical clarity for founders, operators, and technical leaders.


[…] Serverless Computing in 2026 – Complete Guide to Benefits, Trade-offs & Use CasesBy Tech Expert TeamClear, practical guide to serverless computing in 2026. Learn how it works, real benefits and limitations, ideal use cases, cost realities, and when traditional or container-based approaches are still better. Leave a Comment […]
[…] Serverless Computing in 2026 – Complete Guide to Benefits, Trade-offs & Use CasesBy Tech Expert TeamClear, practical guide to serverless computing in 2026. Learn how it works, real benefits and limitations, ideal use cases, cost realities, and when traditional or container-based approaches are still better. 1 Comment […]